Category: Professional

  • ORDER!

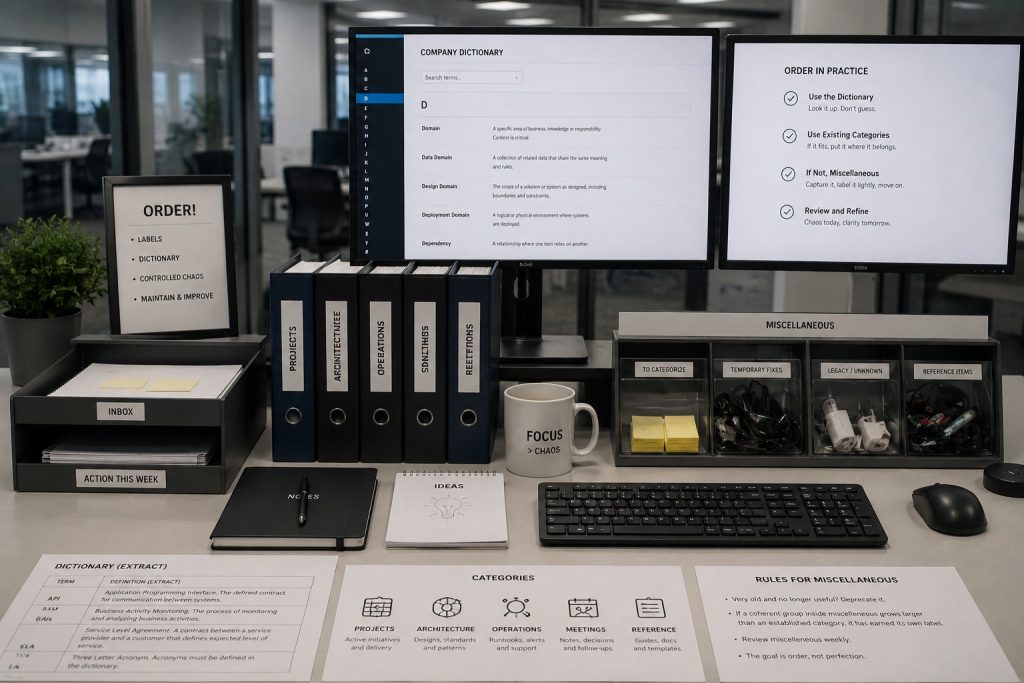
    ORDER!

    Survival games have given me a very practical appreciation for labels. At the beginning, everything fits in one box. Later, I spend half my time opening boxes because I know I put a particular tool somewhere.

    A sign saying wood or tools saves a surprising amount of effort.

    I think about enterprise systems in a similar way. A service name, a team name or an acronym should help someone find the thing they need. When the same label means several things, people can spend an entire meeting agreeing with each other while imagining different systems.

    Put the meaning where people can find it

    Take the word domain. It could mean a DNS domain, an identity domain or a business area. I would put those meanings in one searchable index with links to the teams that maintain the definitions. A common place to look is useful even when different teams legitimately use a word differently.

    I would keep each entry short:

    • Term and context.
    • Definition and owner.
    • Related systems.

    For a business term such as available stock, I would add the calculation and an example. If warehouse and sales need different definitions, name those variants and explain their relationship. Forcing both into one vague sentence loses information.

    This can start as Markdown in a shared repository or a maintained page in the company wiki. The useful part is the agreement to update it when a contract or system changes. A glossary that requires a separate annual clean-up project will spend much of its life out of date.

    Give services a stable identity

    Names change when teams reorganize. I would give an integration a stable identifier and keep its display name separate. That identifier can appear in deployment configuration, logs, dashboards and runbooks. Searching for it should lead to the same flow even after the team owning it has changed.

    id: warehouse-stock-import
    displayName: Warehouse stock import
    owner: warehouse-integrations
    source: warehouse
    target: erp
    contract: StockSnapshot.v1
    runbook: docs/runbooks/warehouse-stock-import.md
    status: active

    This is an illustrative catalog entry. In a real repository I would validate required fields in the build and check that the runbook path exists. A link to the owning team’s maintained contact page is better than copying a person’s name into ten configuration files. The catalog can stay small until there is a reason to automate more of it.

    Keep a place for the awkward things

    I still want a miscellaneous category. There will be a one-off PowerShell fix, an unexplained mapping exception or a small experiment that does not yet deserve its own structure. Making a home for those things is more practical than stopping every task to invent a taxonomy.

    Before running that script

    Even a miscellaneous script needs a few facts. I would record who added it, why it exists, which environment it affects and whether it is safe to run more than once. A production SQL correction should also have a review and a record of the affected keys. Calling it miscellaneous should have no effect on the access or review it requires.

    For an experiment, I would add a review date and a sentence describing what would make it worth keeping. That gives future me a starting point. A directory of scripts named final-fix-2 tells me very little about whether any of them should still be used.

    Let repeated work suggest the next category

    Suppose miscellaneous starts filling up with failed-message replays, mapping overrides and stock corrections. I would look at the reasons they are needed. Perhaps several are compensating for the same missing validation in the source. Perhaps the operator interface needs a supported correction function.

    Grouping those scripts under manual interventions is useful if it leads to shared controls: input validation, a preview of affected records, an audit entry and a documented recovery step. Moving them into a neatly named folder without changing how they are used buys much less.

    I would review a small portion of the list regularly, beginning with the items that touch production or get used repeatedly. Retire a script when its replacement is in service and its retention needs have been handled. Keep an archive record explaining the replacement so an old support note still makes sense.

    Make the structure earn its upkeep

    A label is doing its job when someone can find the right service, understand what it owns and reach the people responsible for it. I would test the catalog by asking a colleague unfamiliar with a flow to locate its runbook and explain how to recover a failed message. The points where they get stuck show what needs improving.

    That is the level of order I am after. I want enough structure to stop losing tools in boxes, and enough room to keep the odd useful thing until I understand where it belongs. In a software estate, stable identifiers, a searchable vocabulary and a small amount of maintained metadata go a long way.
  • Local AI Workflows: Building an Incident Assistant

    Local AI Workflows: Building an Incident Assistant

    The local AI workflow I would start with is an incident assistant for an integration team. An operator selects a failed flow, and the assistant prepares a short note containing the observed error, relevant runbook passages and a suggested next check. That is a small enough job to test properly.

    The operator can open the sources and decide what to do.

    The attraction of running it locally is straightforward: the selected operational context can stay on company infrastructure, and a repeated summary has no external model token charge. There is still a machine to operate and software to maintain. I would make the first version useful on one class of incident before trying to give it access to the whole estate.

    Define the result before choosing the model

    Take a warehouse reservation timeout. The useful output would identify the affected integration, when the timeout occurred, whether a booking or reservation reference was received, and the runbook section for checking an uncertain outcome. It should distinguish recorded facts from suggested explanations. An invented statement that the warehouse is down could send the operator in the wrong direction.

    I would ask for a compact structured result: summary, observedFacts, suggestedChecks and sourceIds. The application validates that shape and verifies that cited source IDs were actually supplied to the model. A valid structure alone says nothing about whether the explanation is correct, so the interface should show the original error and cited passages beside the draft.

    A concrete first implementation

    One possible stack is an internal ASP.NET Core application, a PostgreSQL database holding approved documentation and incident metadata, and Ollama serving a local Qwen3 8B model. This is a proposed starting point, not a claim that I have benchmarked it for every company. The model needs to fit in memory with the chosen context size, and the team needs to test its language and task quality.

    The application handles identity and retrieves context before calling the model. Ollama should be reachable only from the application or a controlled administration path. The browser does not need direct access to the model server. I would begin with one concurrent generation, a bounded queue, a request timeout and a clear busy response when capacity is exhausted.

    Each request should include an integration ID and a bounded time window. The server retrieves a small set of relevant errors and the approved runbook for that integration. It then sends only that material and the task instructions to the model. That keeps the first implementation understandable and gives us a way to inspect exactly what produced an answer.

    Start retrieval with identifiers and text search

    For an error code such as WH-RESERVATION-TIMEOUT, an exact match against a maintained runbook is a good first retrieval method. PostgreSQL has full-text search for broader document queries. I would combine explicit integration and error-code filters with text search before adding a vector index.

    Each stored passage needs a document ID, version, source URL or path, last-reviewed date and access information. When a runbook changes, the index should update or remove old passages. Otherwise the assistant can give technically plausible advice for a retired version of the integration.

    Embeddings may help when people describe the same issue in different words. I would add them if a test set shows that useful passages are being missed. That introduces another model, an indexing job and a decision about chunk size. Those are manageable tasks, but I want a measured retrieval problem to justify them.

    Enforce access before building the prompt

    Apply permissions during retrieval

    The server must apply the user’s access permissions during retrieval. Telling the model to ignore restricted documents is too late once their contents are already in the prompt. The same rule applies to cached answers: a result produced for one user cannot be reused for another without checking what information it contains.

    Incident text and documents can contain misleading instructions, either deliberately or by accident. I would treat them as data and keep the first assistant read-only. It gets no shell, database write access or replay endpoint. A suggested command can be displayed as a draft for review. Executing it would be a separate feature with explicit authorization and an audit trail.

    Logs also need filtering before indexing. Credentials, access tokens and full customer payloads usually add risk without improving the incident explanation. An allowlist of useful fields is easier to reason about than hoping a later redaction step catches everything.

    Measure what the operator can use

    I would collect thirty representative, sanitized incidents and write the expected facts and useful source passages for each. Include missing logs, contradictory timestamps, a retired runbook and an error with no known procedure. Someone familiar with the integrations should judge whether the suggested next check is supported by the evidence.

    For each run, record:

    • Retrieval quality and unsupported claims.
    • Edits needed and response time.
    • Whether the operator could finish the note sooner.

    Compare against opening the runbook directly. If retrieval finds the wrong procedure, changing the generation model may leave the underlying problem untouched.

    Record model identity, prompt version and document versions with the test results. Run the same examples when any of them changes. Keep the previous model and configuration available so an update can be rolled back if familiar incidents start producing worse advice.

    Budget for the complete request

    Local cost includes hardware, electricity, storage, patching and the time spent maintaining the documents and application. Measure electricity at the wall over a representative workload. For capacity, include retrieval, prompt processing, generation and time waiting in the queue. A generation-only tokens-per-second result overstates what an end user receives across the complete workflow.

    Ollama’s generation response exposes timing and token-count fields that can help with these measurements. I would also record total request duration at the application boundary. Compare cost per accepted incident note, including retries, against any external alternative being considered.

    An external model can remain an explicitly selected option for approved data. Automatic fallback deserves particular care: a local outage must not silently change where incident information is processed. The workflow should have a visible failure mode when a request cannot be completed under its data-handling rules.

    The first delivery

    I would deliver one working incident type, a small approved document set, a quality report, a restore procedure and a list of cases the assistant cannot handle yet. That gives the team something they can use and improve. Additional integrations can follow once their runbooks, access rules and examples are ready.

    The company then owns a useful piece of application logic: selecting context, controlling access, recording evidence and reviewing a draft. A model replacement still needs testing, but those parts can remain in place. That is the practical reason I would put effort into a local workflow.

  • Integration platform vs ETL/AI cloud platform

    Integration platform vs ETL/AI cloud platform

    The seafood company in this series needs to reserve stock when an order is accepted. It also needs to analyse production yield over several years. Both jobs move data, and the same cloud product may be capable of parts of both. I would still design their recovery paths separately because a warehouse load and a stock reservation have different consequences when they run twice.

    The boundary I care about is the business action. A pipeline that reloads yesterday’s production data can be useful. A replay that books the same truck again needs a different set of controls. Product names alone tell us very little about whether those controls exist.

    Work backwards from the booking

    For transport booking, I would define a request identity that remains stable through retries. The integration records the request before calling the carrier and stores the carrier’s booking reference when it receives an answer. If the call times out, recovery queries the carrier using that identity where the API supports it.

    An uncertain outcome stays visible until it has been reconciled.

    Booking and recovery

    An Azure Service Bus queue and a .NET worker are a plausible implementation. The queue holds accepted work while the carrier is unavailable. The worker owns the carrier contract and retry behaviour. A separate process table records pending, confirmed, rejected and uncertain outcomes. Those states let operations distinguish a request waiting to be sent from a booking that may already exist.

    Status and reporting

    The ERP can expose the booking status to users. The data warehouse can receive confirmed booking events through its own consumer. This allows reporting to catch up after an outage without becoming part of the carrier call’s success path.

    Give the analytical load its own recovery model

    For production analysis, I would keep the original extracted records in a restricted landing area with a source identifier, extraction time and source revision. Azure Data Factory could orchestrate extraction and copying into storage. SQL transformations or another data-processing runtime could then build the reporting tables. The exact runtime depends on volume, team skills and the transformations required.

    Publish an accepted load

    A load should have a runId and a manifest. I would validate row counts, required fields and key uniqueness before publishing the result. If a partition is replaced during recovery, consumers should see a complete accepted version. The reporting model also needs explicit rules for corrections: a revised batch weight may require recomputing yield for an earlier day.

    Duplicates and late data require deliberate treatment in analytics too. A duplicated production row can change a forecast just as surely as it changes a report. An upsert keyed by source record and revision, or a deduplicated transformation over retained history, makes the rule inspectable. Choosing between them depends on whether the report needs current state, an audit history, or both.

    Define the timestamps and quantities

    For a batch record, I would carry batchId, producedAt, receivedAt, sourceRevision, weight and unit. Quality approval should have its own status and approval time. Production completion and quality approval describe different events; the data model needs room for both.

    The stock measure needs equally careful naming. Physical stock, reserved stock and available-to-promise stock answer different questions. I would keep their definitions beside the dataset and test them against a few known orders. A forecast trained on physical stock when its users expect available stock starts from the wrong quantity even if every pipeline is green.

    Keep independent progress for each consumer

    Billing, transport and analytics should each be able to pause and recover within their agreed limits. With a topic-based design, each consumer gets its own subscription and dead-letter handling. For a retained event stream, consumers need independent checkpoints and a retention period long enough for their recovery requirements.

    This independence has a storage cost. A stopped consumer accumulates work until its retention limit is reached. I would alert on its lag and agree how to rebuild it from the source or retained history. A line on a diagram labelled replay is incomplete until somebody knows where the replay data comes from and which side effects it may repeat.

    Sharing a platform can still be practical

    The same team, deployment tooling or cloud estate can support both workloads. I would separate identities, access permissions, capacity limits and recovery procedures where a failure could cross the boundary. A large historical reload should have a way to slow down before it exhausts resources needed by today’s orders.

    A data platform can also produce an operational recommendation, such as a proposed replenishment order. In that case I would expose the recommendation with its calculation time and model version, then submit an explicit command through the operational application’s validation rules. The application checks current stock, limits and approvals before accepting it. Recomputing a prediction should have no accidental purchasing effect.

    A useful first test

    I would stop the analytical consumer for two hours while continuing to accept orders and book transport in a test environment. After restoring it, I would reconcile the reporting totals and inspect any duplicates or corrections. Separately, I would force a carrier timeout after acceptance and check that recovery finds the existing booking.

    Those two tests make the separation tangible. They tell us whether analytical recovery can proceed independently and whether operational retries preserve the intended business result. That is enough direction to evaluate a proposed platform without requiring every team to buy a different product.