A direct integration is often a reasonable first choice. If one system needs a small daily extract from another, a scheduled transfer can be easy to build and easy to explain. The trouble starts when more processes begin depending on that transfer and its original assumptions stay buried in the script.
Consider a fictional seafood processor with an ERP, warehouse, production system, transport portal and reporting database. Sales uses warehouse stock to promise deliveries. Production updates the available lots. Quality approval determines which lots can ship. A stock export now carries several decisions that matter to people outside the warehouse team.
Follow one stock update
Suppose a PowerShell task exports stock every fifteen minutes and uploads a CSV to the ERP. At 18:00 on Friday the export fails. Both applications remain available, and the scheduler may even report success if the script caught an exception without returning a failing exit code. Sales keeps reading the last imported quantities.
I would give that transfer a manifest containing an exportId, source timestamp, row count and checksum. The receiving job should record when it finished validating and applying the export.
A successful file upload tells us about transport; we also need the import outcome before treating the stock as current.
For a full snapshot, I would load into staging, validate the rows and publish the new snapshot atomically where the database design allows it. Replacing half the stock table before discovering a malformed row leaves readers with a mixture of two exports. A staging table also makes it easier to inspect rejected data without disturbing the last accepted snapshot.
Make freshness part of the interface
Freshness is part of the contract
The stock response should carry an asOf timestamp. If the business agrees that stock older than thirty minutes is unsuitable for a delivery promise, the consuming application can flag it and ask for confirmation. Thirty minutes is an example threshold, not a universal integration rule. The warehouse and sales teams need to decide what delay they can tolerate.
I would alert on the age of the last successfully applied export, with separate alerts for transfer failure and validation failure. This catches a job that never starts as well as one that crashes. Counting exceptions alone misses both a disabled scheduler and a script that keeps producing yesterday’s file.
Changes expose the real dependencies
A new warehouse version might change availableStock from individual units to cartons. The CSV still parses and all HTTP calls still return success. A contract test should catch that by checking representative items against agreed units and values. The same applies to cancelled orders, deleted items and time zones.
With incremental extracts, I would document the cursor and deletion behaviour. A query based only on LastModified greater than the previous run time can miss records when timestamps collide or commits become visible late. A supported change feed is preferable where available. Otherwise the extraction design needs a stable ordering key, an overlap strategy and deduplication, plus a way to reconcile the full source periodically.
This is where several independent scripts become expensive. Each one can implement a slightly different definition of stock, retry policy and cursor. A warehouse change then requires finding and testing every copy. A shared, versioned contract gives consumers a common interpretation even if several runtimes continue to carry the data.
Count the dependencies you actually have
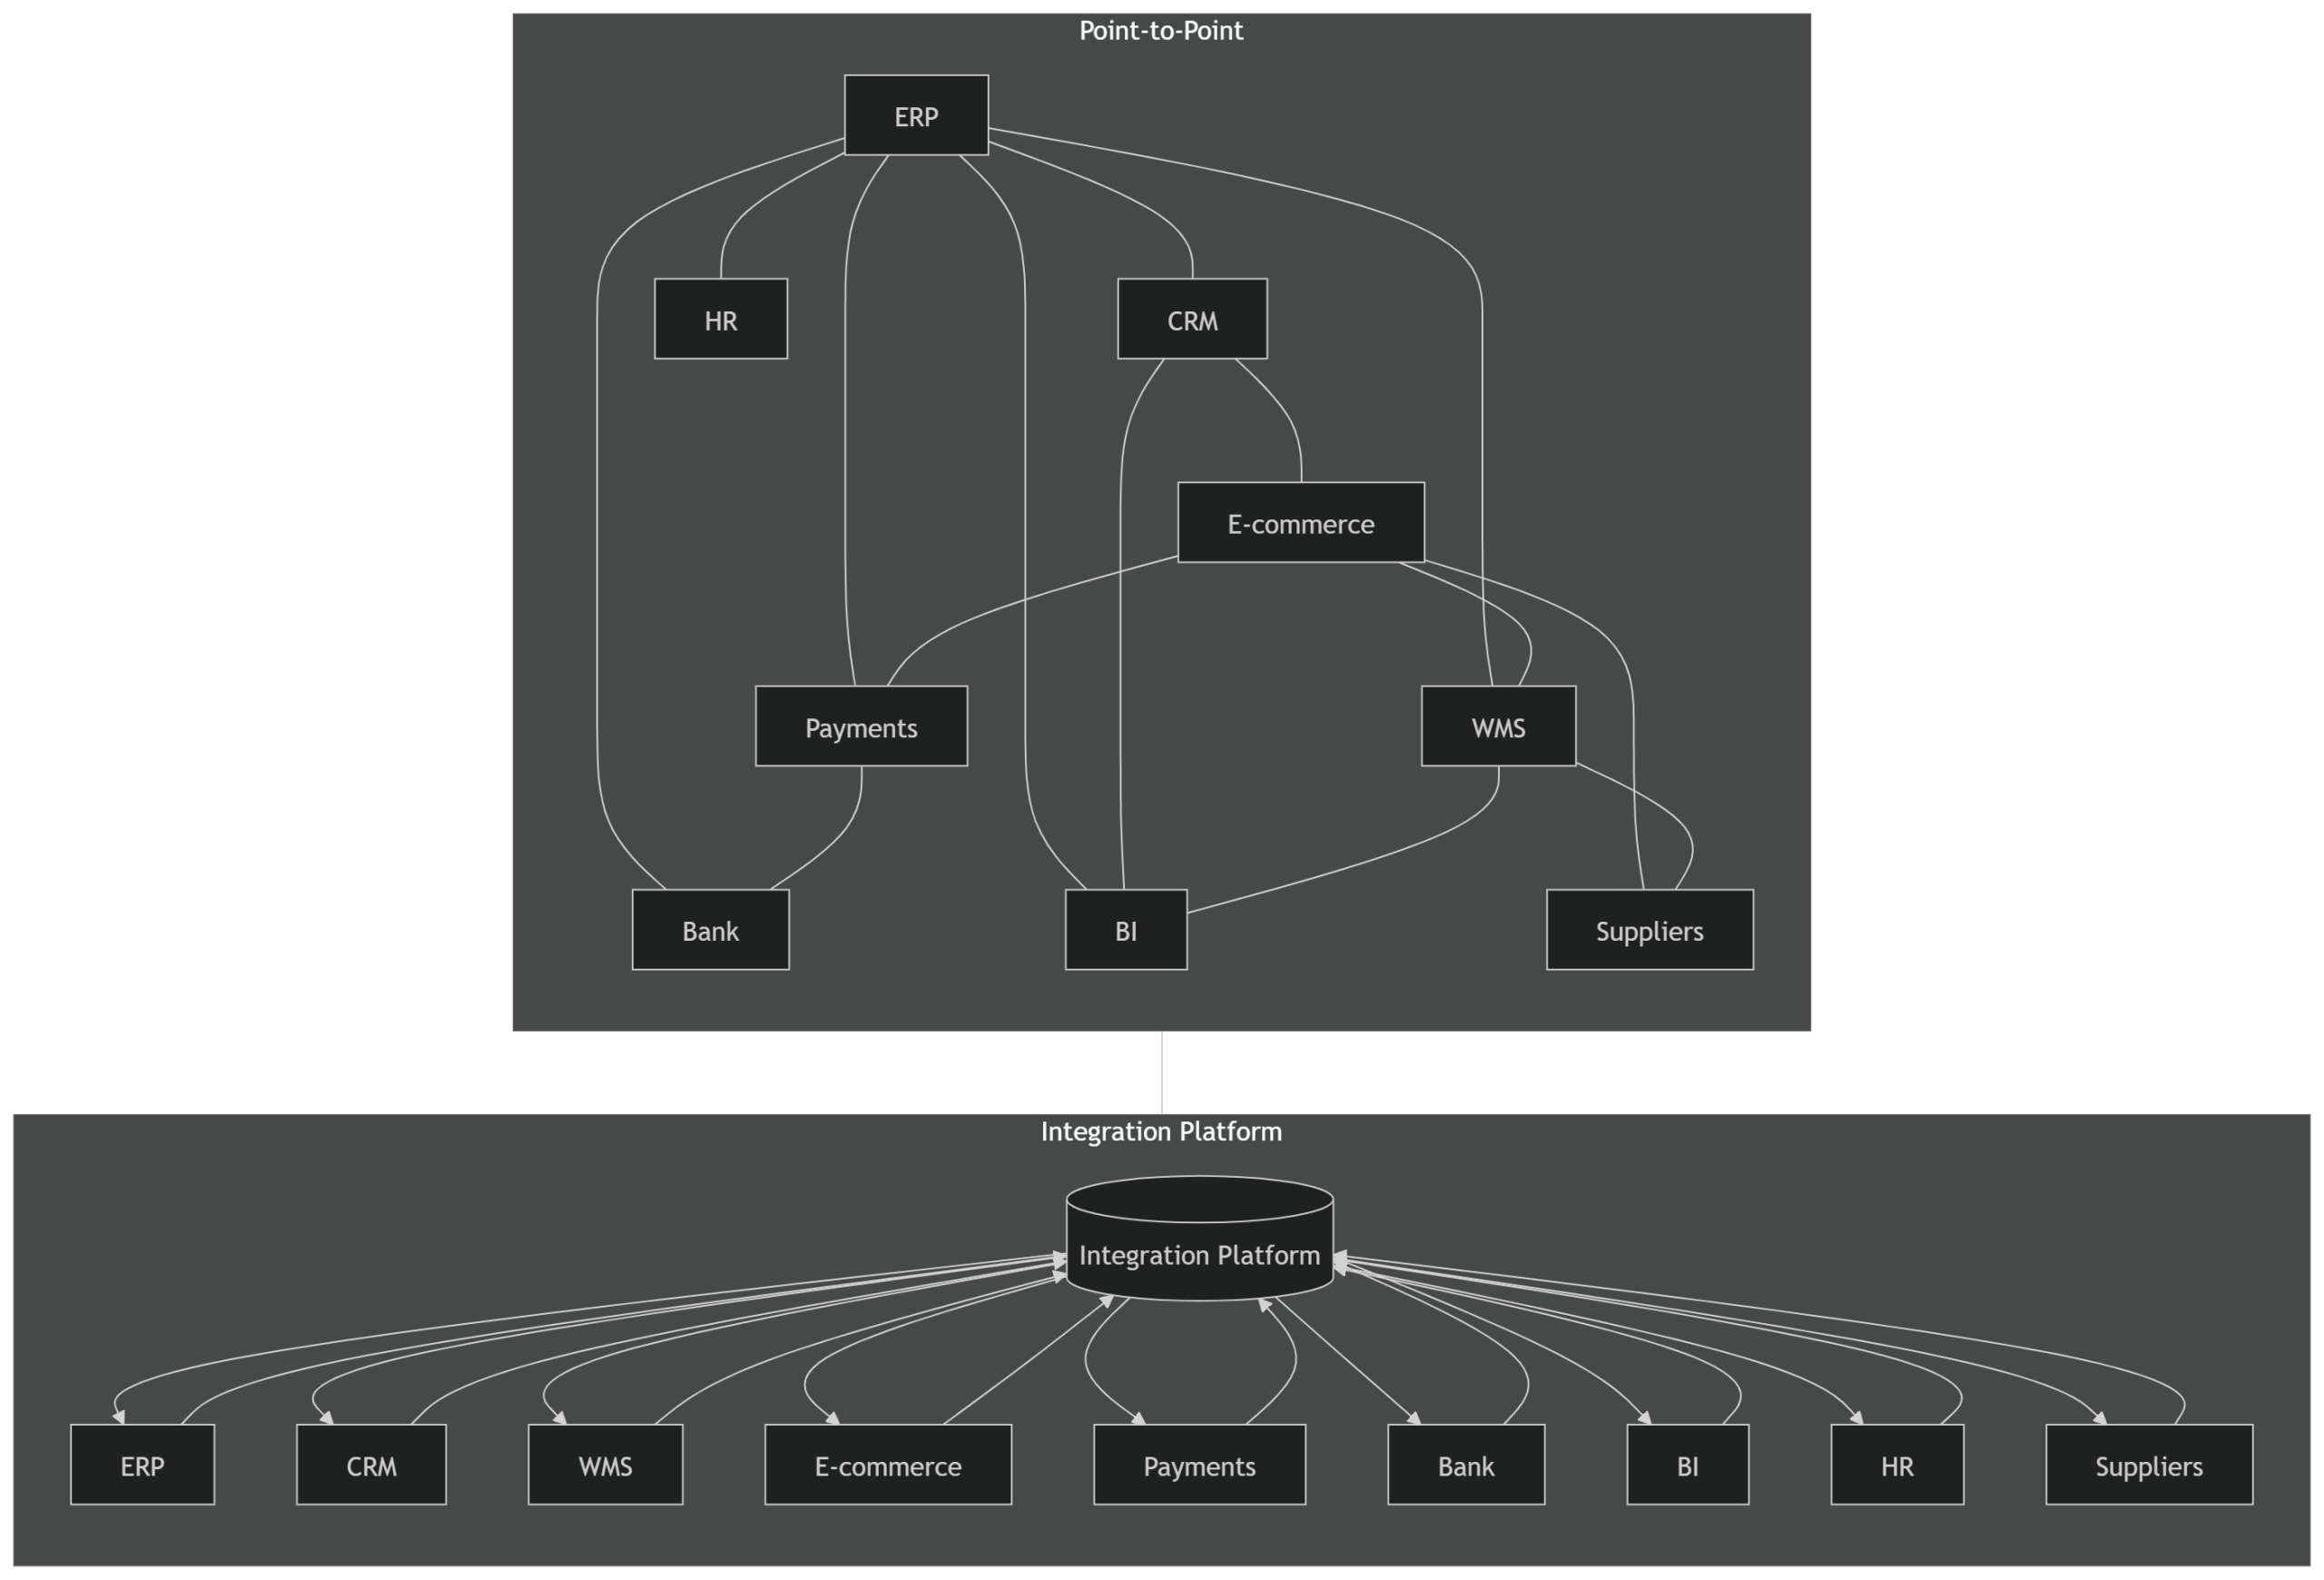
For n systems, n × (n − 1) / 2 is the number of possible undirected pairs. Ten systems gives 45 pairs. That is an upper-bound illustration for a fully connected graph; it is not a prediction that every estate has 45 integrations. Direction, multiple contracts between the same systems and differing business rules complicate the count further.
I would inventory the real flows instead. For each one, record the source, consumer, contract, schedule, credentials owner, last successful run and recovery method. Then ask which source changes require coordinated releases. That list is more useful for planning than a dramatic connection-count diagram.
Improve the existing path before replacing it
My first change would be to put the export code and its configuration template in version control, give it a maintained service identity and make failed runs fail visibly. Then I would add staging, freshness monitoring and a replay procedure using the original exportId. These changes can improve a scheduled transfer without a platform migration.
A durable broker becomes useful when several consumers need independent retries, when the source must keep working during a target outage, or when the delay needs to be much shorter than the schedule. Each subscriber then needs its own progress and error handling. Moving the same undocumented payload onto a topic leaves the contract problem in place.
I would start the migration with the flow causing the most operational pain. Disable its target during a test, restore it and check the recovered stock against the source. Repeat an export and verify that quantities stay correct. That gives a concrete basis for deciding which shared platform capabilities the next integration actually needs.